The problem
Creating a taxonomy for a new feedback domain took a seven-notebook workflow. Scientists picked examples, tuned prompts, ran clustering, and stitched a three-level hierarchy by hand — five to seven days of expert time per domain, with a scientist in every step.
What I built
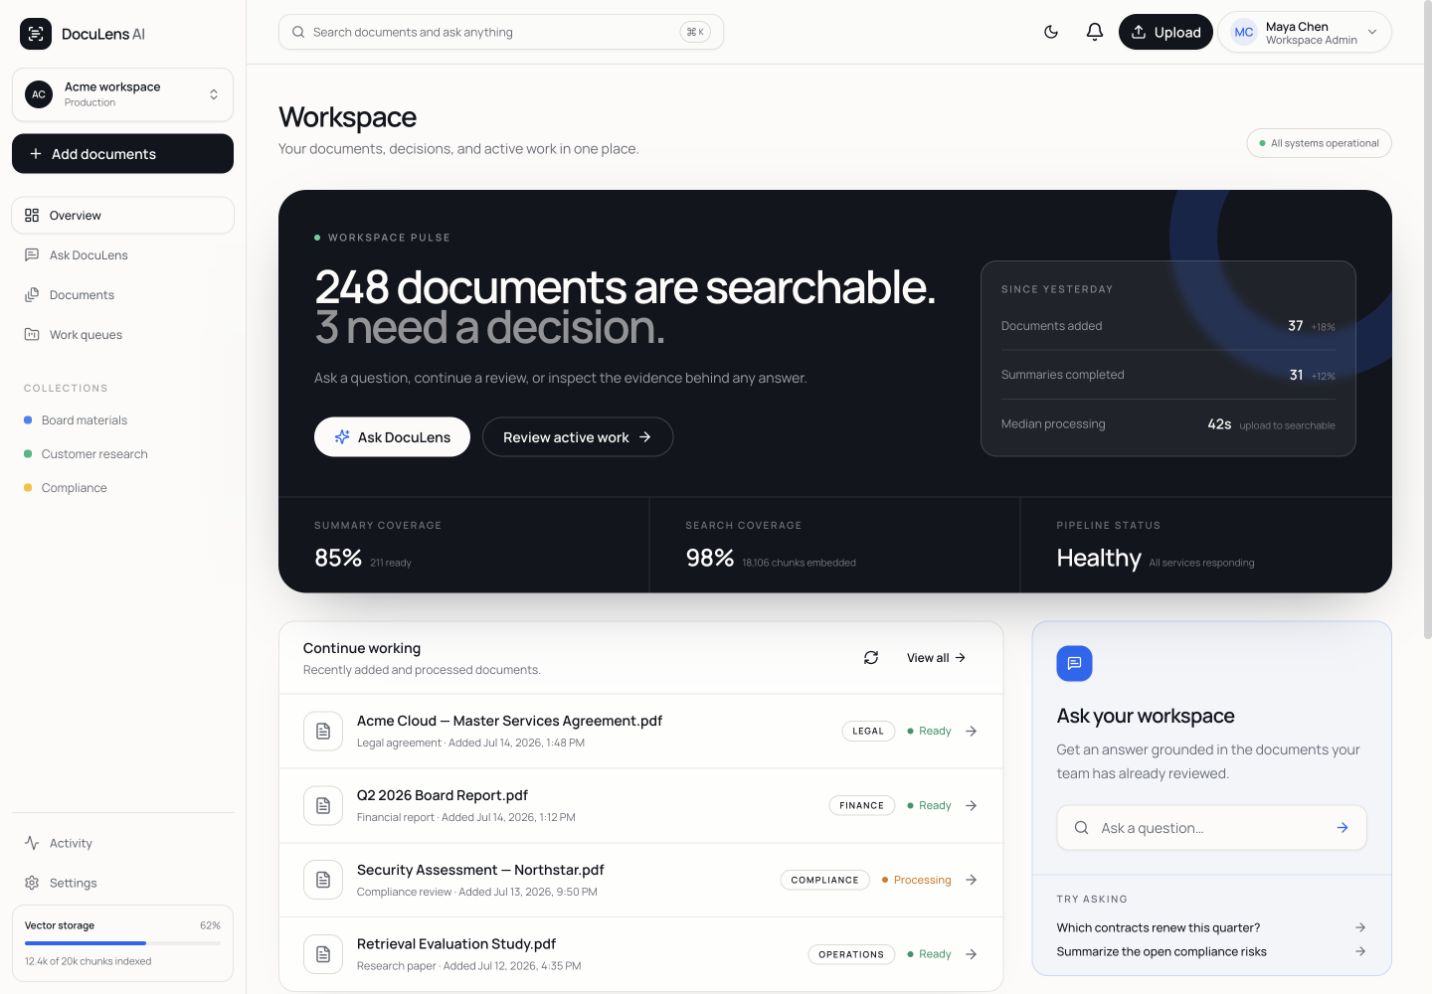
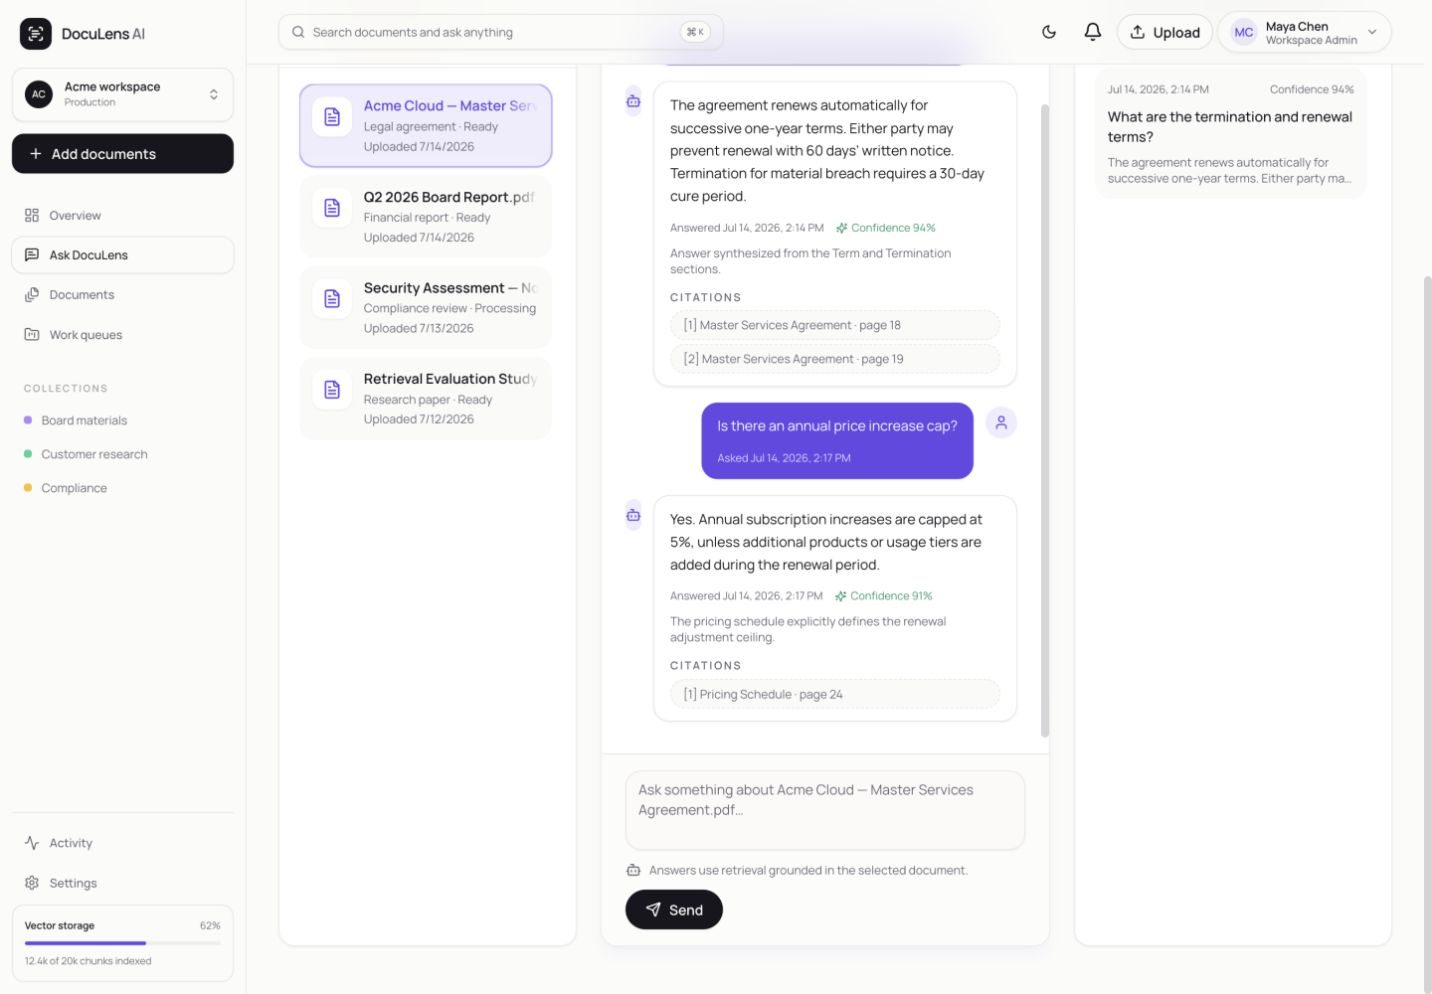
A self-calibrating knowledge-extraction and taxonomy-induction system, shipped as a production container for multi-domain, million-record workloads.
Approach
- Mine and validate a small, diverse in-domain example set, then run cached batch extraction at scale.
- Density-based L3 discovery over structured phrases; the LLM classifies those clusters into a disjoint hierarchy.
- Deterministic attribution computes every quality claim before the LLM renders it in plain language.
What changed
- 0.74
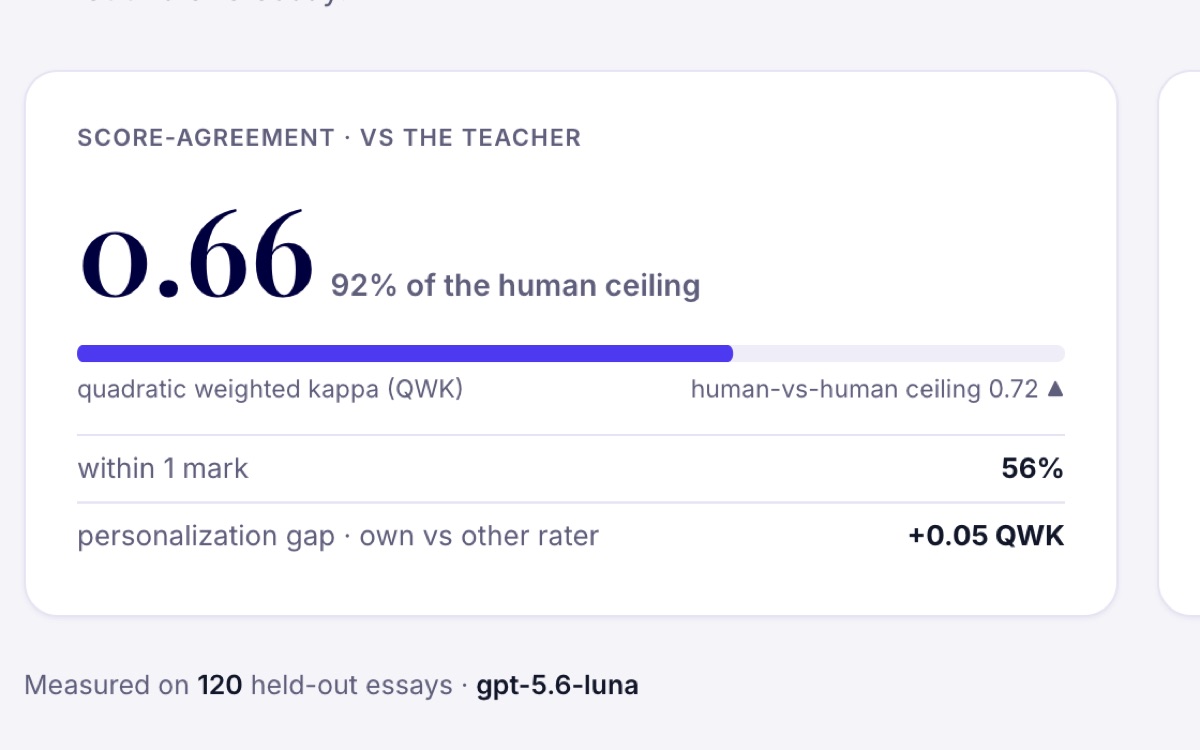
- taxonomy F1, against a 0.71 manual scientist baseline
- <18h
- autonomous run, down from a five-to-seven-day workflow
- 23.8% → 0.7%
- missing Category and Aspect extractions
- 2.7× / 53%
- faster extraction, lower inference cost
- 12 teams
- adopted the explainable evaluation framework
1 of ~200 Applied Scientist interns across India. Selected via Amazon ML Summer School 2025 — 3,000 of 1.6 lakh applicants.
Read the full case study